I spend most of my career sitting between two groups who rarely speak the same language. Recruiters think in candidates, pipelines, and offers. Engineers, on the other hand, think in tables, keys, and constraints. My job as a data architect is to translate between them. Nowhere has that translation been trickier than in recruitment database design.
A hiring system looks simple from the outside. Post a job, collect resumes, schedule interviews, make an offer. Underneath, though, it is one of the messiest data problems in HR data architecture. The data arrives unstructured. The workflow changes every quarter. Volume, meanwhile, swings wildly with hiring season.
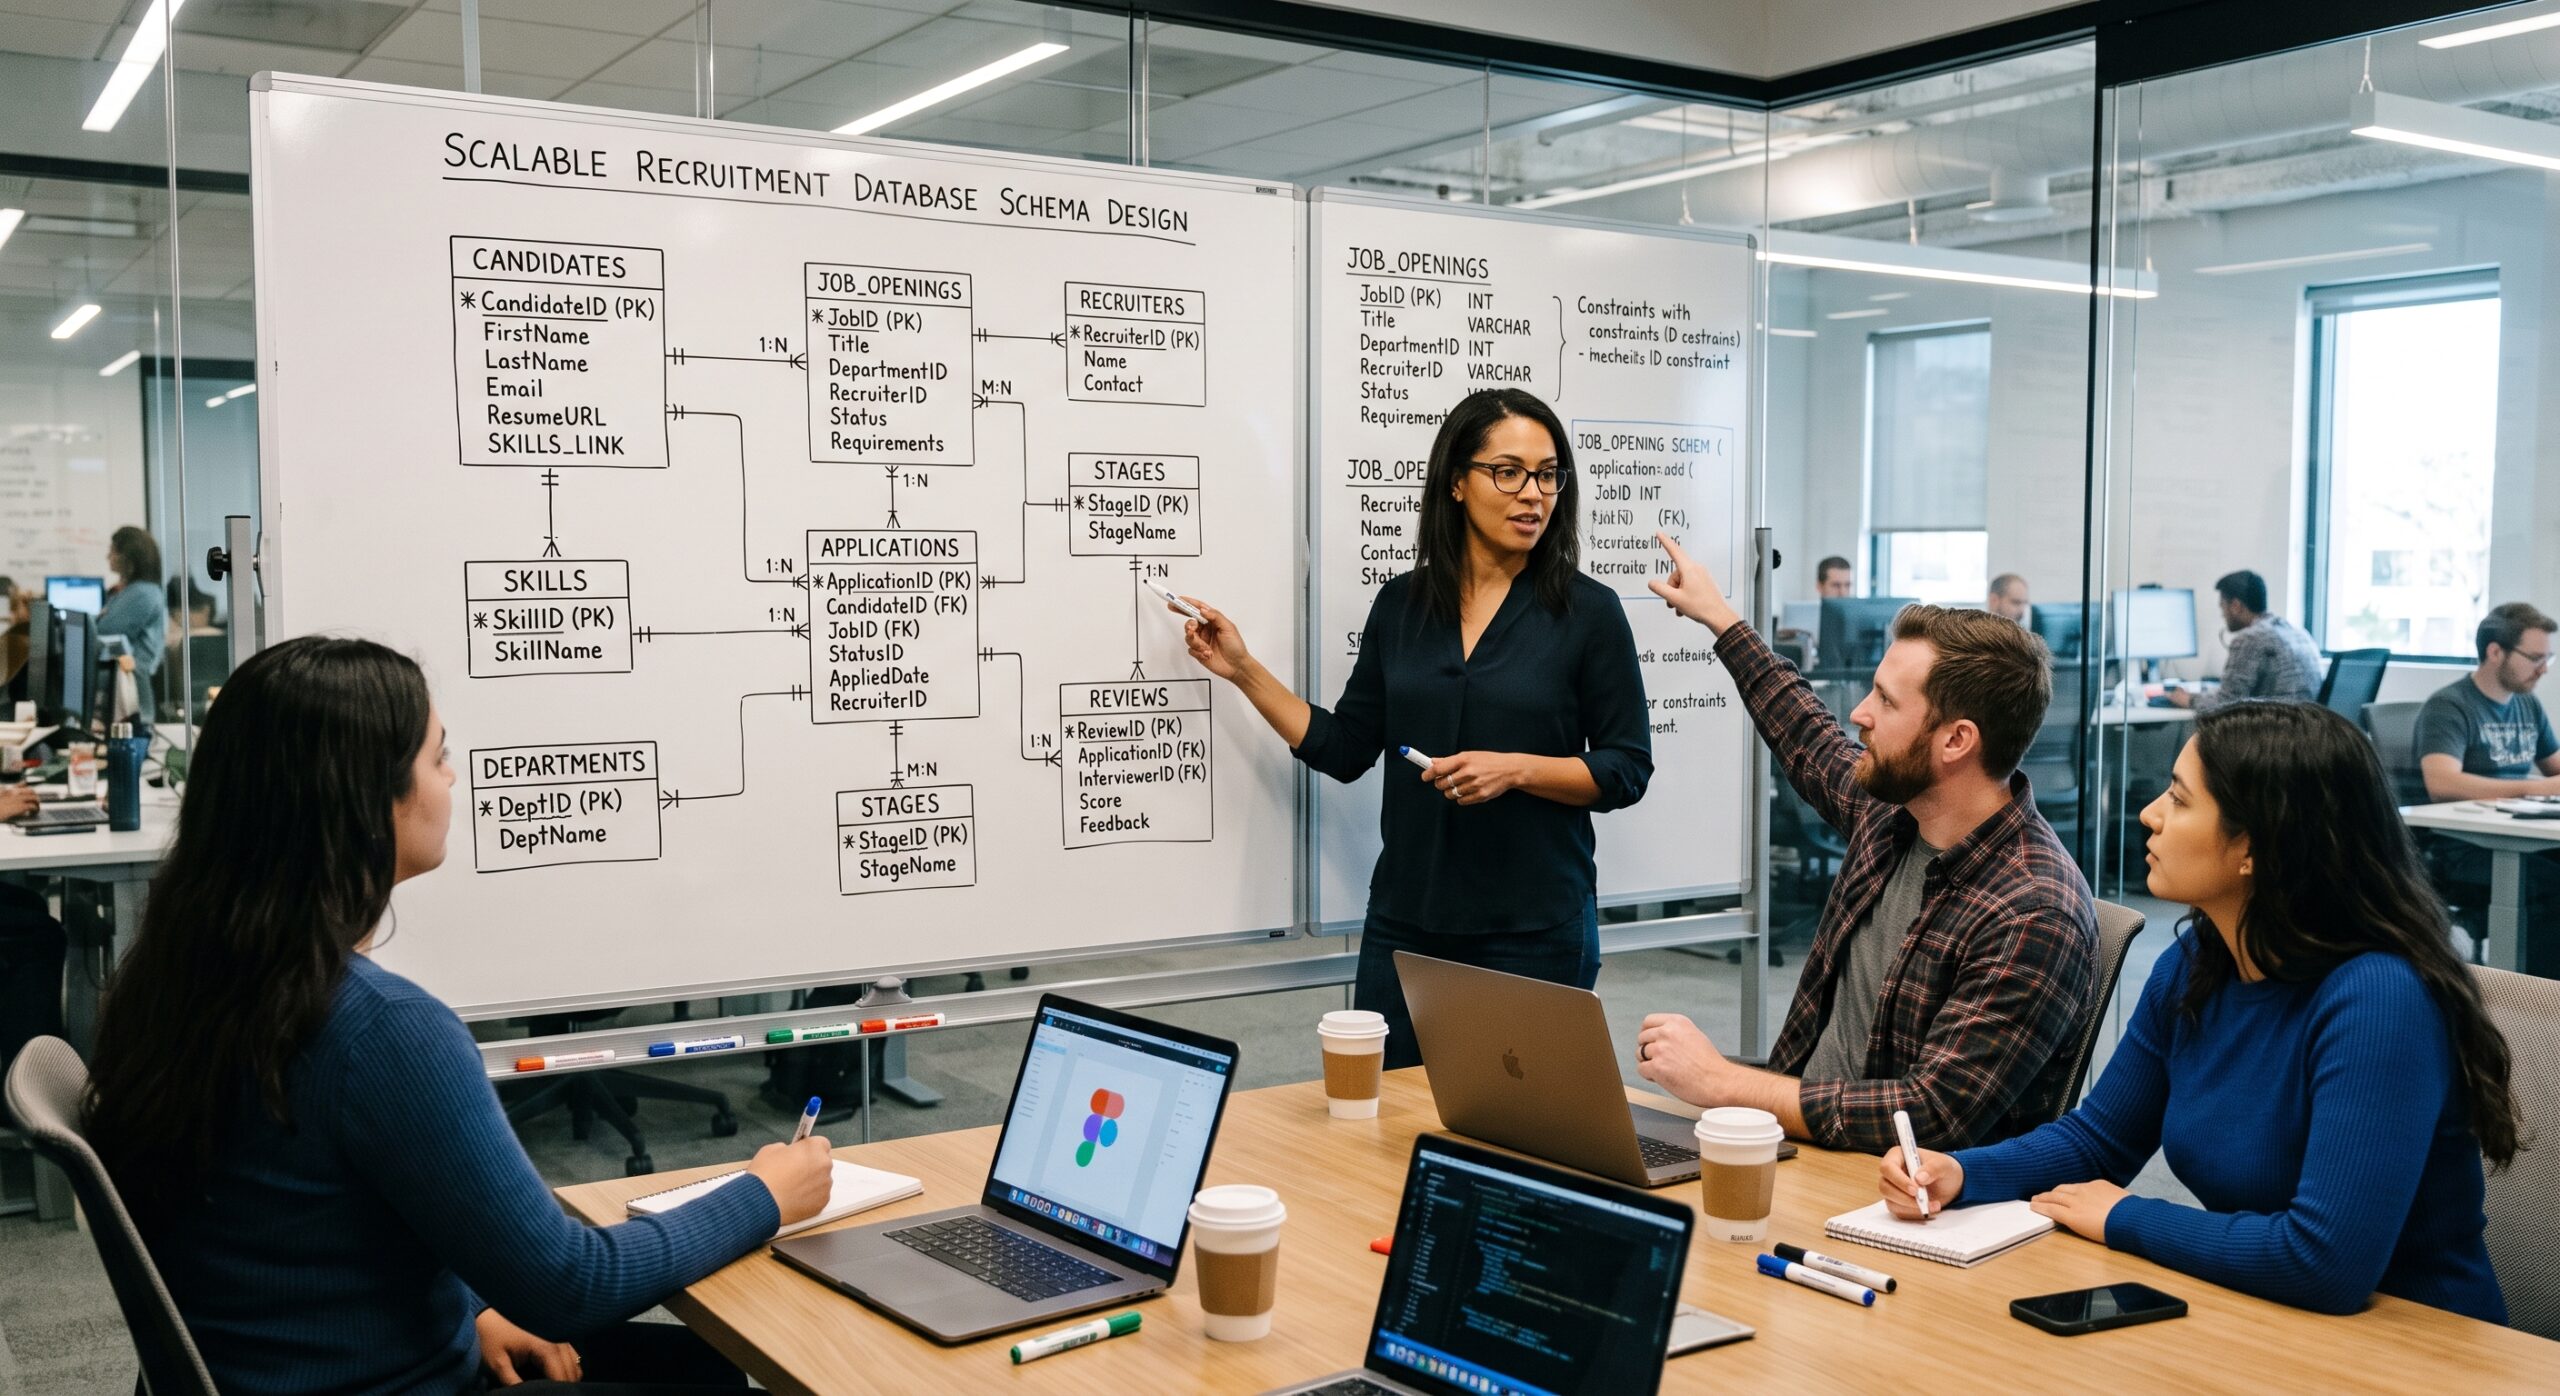
This article walks through my approach to recruitment database design from scratch. It covers which entities matter, how to model the relationships between them, and where normalization helps. It also covers the ERD habits that keep a schema readable two years later. Every pattern here, in fact, came out of a real project, usually after the first version of the recruitment database design broke under real usage.
What Makes Recruitment Database Design Different
A payroll database stays fairly calm. Employees join, get paid on a schedule, and leave. A recruitment database, by contrast, has to model a process that never sits still. A candidate might apply for three roles at once, drop out of one pipeline, and then reapply six months later. At the same time, a current employee might refer that same candidate for a completely different position. So the schema has to absorb all of that without collapsing into a tangle of exceptions.
Source Diversity
Candidates come from job boards, referrals, agencies, career fairs, and inbound applications. Each source, however, carries different metadata. For example, a referral needs a link back to the referring employee. An agency submission, similarly, needs a contract and fee reference. A career fair lead, meanwhile, might have nothing more than a name and a phone number. Because of that variety, your schema has to hold all of it. It cannot force every source into the same rigid shape.
Constantly Changing Application State
A single application moves through screening, phone interview, onsite rounds, reference checks, and an offer decision. Along the way, recruiters can reject and reopen it. They can also pause it for budget reasons or merge it with a duplicate. If you hardcode status as one column on the application table, though, you lose the history of how it got there. Recruiters, as a result, will ask for that history within the first month.
Compliance Pressure
Candidate data includes resumes and, in some cases, health or disability disclosures tied to accommodation requests. It includes personal contact details too. Privacy regulations covering this data vary by country and even by state. So retention rules are not optional. Instead, your schema needs to enforce them, rather than rely on someone remembering to run a cleanup script.
The Core Entities Every Recruitment Database Needs
Strip away the vendor specific extras. Almost every applicant tracking schema I have built or reviewed comes back to the same 7 entities. Once you get these right, everything else becomes refinement, and these 7 entities are the backbone of solid recruitment database design.
Candidate and Job Requisition
Candidate holds the person, independent of any specific job. Name, contact details, resume file references, source, and consent flags for data retention all live here. A candidate should exist once in your system, even after ten applications over three years. That means you need a reliable way to catch duplicates by email or phone. Otherwise, you end up creating a fresh row every time someone reapplies.
Job Requisition, meanwhile, represents an open position. It carries title, department, hiring manager, headcount, and a status such as draft, open, on hold, filled, or cancelled. This differs from a generic job catalog entry. A requisition, after all, ties to a specific budget line, not a reusable job description.
Application and Stage History
Application bridges a candidate and a requisition. Since most of the interesting behavior lives here, give it its own primary key. Do not treat it as a simple join row, because an application accumulates its own history, documents, and evaluations over its lifetime.
Application Stage History, in turn, records every transition an application makes. Each row logs a timestamp, the stage entered, and who moved it. This is the table that saves you when a director asks why a candidate sat in screening for five weeks. The answer, after all, lives in the timestamps, not in your memory.
Interview and Evaluation
Interview covers scheduled and completed interview events. It links to the application, the interviewer or panel, the format, and the outcome. Interviews often carry a many to many relationship with interviewers, which the next section covers.
Evaluation, sometimes called a scorecard, stores structured feedback tied to a specific interview or stage. It typically holds a rating plus free text notes. Keep this separate from the interview record. That way, multiple interviewers can submit independent evaluations for the same event, without overwriting each other.
Offer
Offer captures compensation, start date, approval chain, and acceptance status once a candidate clears the process. This table lives apart from the application table on purpose. After all, offers carry their own approval workflow, and they often need to integrate with a separate compensation system.
Those 7 tables will not cover every edge case a large enterprise ATS needs. Still, they form a foundation that scales cleanly. From there, referral tracking, agency contracts, and background check status tend to attach onto this core rather than replace it.
Modeling the Relationships Correctly
Getting the entities right is only half the job. The relationships between them, in fact, are where recruitment database design tends to go wrong. Usually, someone reaches for a one to many relationship where a many to many one belongs, or the other way around.
One to Many Relationships
Candidate to Application is one to many. One candidate can have several applications, one per requisition. The application table carries the foreign key back to the candidate. Resist the temptation, though, to store multiple job interests as a comma separated list on the candidate record. I have inherited databases with exactly that pattern. Every report built on top of it needed string parsing, and eventually it broke the moment someone typed a job title with a comma in it.
Job Requisition to Application is also one to many. Add a unique constraint on the combination of candidate and requisition. That way, the same person cannot accidentally generate two open applications for the same role. This happens more often than you would expect, especially when a candidate applies through two different channels.
Many to Many Relationships and Junction Tables
Interview to Interviewer, on the other hand, is genuinely many to many. A panel interview has multiple interviewers, and any given recruiter or hiring manager sits on interviews for many different candidates. This needs a proper junction table, something like Interview Panelist. Give it its own foreign keys to Interview and to a Recruiter or Employee table. Whatever you do, do not cram interviewer names into a text field on the interview record.
Application to Document follows the same many to many pattern. After all, a single application might reference a resume, a cover letter, a portfolio link, and a reference letter. The same resume file might reasonably attach to more than one application, if the candidate reapplies within a retention window. A junction table, in this case, gives you a clean place to store document type and upload timestamp, without bloating the application row.
Skills deserve the same treatment. Do not treat skills as a free text column on the candidate or the job requisition. Instead, make skills their own lookup entity. Add a many to many junction connecting candidates to skills, and another connecting requisitions to required skills. This is what makes matching and search usable later, since you can query by skill ID rather than run fuzzy text searches against inconsistent free text.
Enforce Foreign Keys
Enforce your foreign keys. Do not just imply them through naming convention. I have watched teams skip foreign key constraints for performance reasons and try to maintain integrity in application code instead. That discipline, however, almost always drifts within a year, once more services start writing to the same tables. So the small overhead of an enforced constraint is worth it. It buys you a real guarantee that an application row can never point to a candidate that does not exist.
Building the ERD: A Practical Sequence
When I build an ERD for a new recruitment system, or redesign an existing one, I follow roughly the same sequence every time. This sequence is what practical recruitment database design looks like day to day, and it rarely fails me.
List Entities from the Real Process
First, list every entity from the business process, not from an existing table structure. Sit with a recruiter or hiring manager. Walk through a real requisition from posting to offer, and write down every noun that comes up. This step catches things engineers miss, such as a second, non scoring interviewer who shadows some interviews for training purposes. That detail, in turn, changes how you model the Interview Panelist junction.
Define Attributes Before Relationships
Next, define attributes for each entity before you draw a single line. It is tempting to jump straight to relationships, but attributes often reveal hidden entities. For instance, suppose interview feedback keeps needing a rating scale, a free text field, and a recommendation flag. That pattern signals a dedicated Evaluation table, not three columns bolted onto Interview.
Normalize to Third Normal Form
Then, normalize your transactional schema to at least third normal form. Every non key attribute should depend on the whole primary key and nothing else. For a recruitment schema, that usually means moving department name and hiring manager email out of the job requisition table. Instead, point them to a proper Department and Employee reference, rather than duplicating that text on every requisition row.
Review with Recruiters, Not Just Engineers
Finally, review the ERD with the people who will actually query it. Recruiters and HR analysts catch modeling errors that a purely technical review misses. After all, they know which questions the data needs to answer. For example, how many candidates came through referrals last quarter, or what does average time to offer look like by department.
Throughout this process, keep the diagram scoped. A single ERD trying to hold candidates, requisitions, interviews, payroll data, and compliance rules all at once quickly turns unreadable. Instead, I keep a core transactional ERD for the hiring pipeline and a separate one for reporting. Then I cross reference the two using shared entity names.
Normalization Versus Performance
A fully normalized schema is the right starting point. This tension, in fact, sits at the center of most recruitment database design work. Recruitment systems, however, also carry reporting demands that fight against pure normalization. Recruiters want dashboards showing time to fill, source effectiveness, and pipeline conversion rates. Those queries, though, can get slow against a deeply normalized schema once you pass a few hundred thousand applications and several years of history.
Denormalize for Reporting, Not for Operations
Because of that tension, my usual approach is simple. Keep the operational tables, the ones your application actively writes to, fully normalized. Then build a separate reporting layer that denormalizes on purpose. This might take the shape of materialized views or, alternatively, a nightly extract into a star schema. That schema needs a central Application Fact table and dimension tables for Candidate, Requisition, Department, and Date. As a result, the operational schema stays clean and enforces integrity, while the reporting layer optimizes for the questions the business actually asks. You can rebuild it from the operational data at any time, so it never risks becoming a second source of truth.
Index and Partition Deliberately
Index the foreign keys you will actually filter and join on. That usually means candidate ID, requisition ID, and application ID. Also index any status or stage column your dashboards filter on heavily. Do not index every column defensively, though, since every index adds write overhead. A recruitment database, after all, can see a genuinely high volume of inserts during a hiring surge.
Once the application and stage history tables grow large, partitioning helps, whether by hire year or by requisition status. This matters most for organizations that must retain years of historical data for compliance but rarely query it. So, after a defined retention period, archive closed requisitions into a separate cold storage schema. That way, the active tables stay fast, and you still keep the data you may need later.
Data Privacy, Retention, and Compliance in HR Data Architecture
Recruitment data ranks among the most sensitive information an organization holds, payroll and benefits aside. Because of that, privacy and retention are not optional extras in recruitment database design. They are part of the job, so the schema itself needs to help enforce compliance. It cannot rely entirely on policy documents that nobody reads.
Build Retention into the Candidate Record
Start by adding a consent and retention field directly onto the candidate record. Capture when the candidate gave consent, what it covers, and when the data is due for deletion. Many organizations, in fact, must purge or anonymize candidate data after a defined window. That window often falls somewhere between six months and two years, depending on jurisdiction. If that rule lives only in a spreadsheet, however, nobody enforces it consistently.
Separate Identity from Evaluation
Wherever you reasonably can, separate identifying information from evaluative information. Interview scorecards and evaluation notes, for instance, do not need to carry a candidate’s home address or phone number directly. Instead, a foreign key back to the candidate record is enough. That choice, in turn, limits your exposure if evaluation data ever surfaces through a reporting tool with looser access controls.
Log Access, Not Just Changes
Log access to sensitive fields, not just changes to them. Knowing who changed a candidate’s status helps. Still, compliance often cares just as much about who viewed a resume or a disability accommodation note. That log matters most when a candidate later raises a complaint about how the team handled their application.
Design for the right to deletion from day one, too. When candidate data sits scattered across a dozen tables with no consistent foreign key discipline, honoring a deletion request becomes an archaeology project. A clean relational structure, on the other hand, turns that same request into a routine task instead of a fire drill.
Common Pitfalls in Recruitment Database Design
A few mistakes show up again and again across the recruitment systems I have reviewed or rebuilt.
Schema and History Mistakes
Treating status as a single mutable column with no history tops the list. The first pipeline conversion report someone requests will need the full stage history, not just the current stage. Retrofitting that after the fact, unfortunately, usually means a painful backfill with incomplete data.
Skipping soft deletes on candidate and application records causes similar pain. Recruiters occasionally need to reopen a closed application, or reference a rejected candidate for a different role later. A hard delete, unfortunately, forecloses that option permanently.
Letting the interview and evaluation model grow ad hoc creates a slow mess too. New columns keep landing on the interview table every time a new interview format shows up. A proper Evaluation entity that flexes through its own attributes avoids that entirely.
Data Quality and Naming Mistakes
Storing job titles and department names as free text, instead of foreign keys, leads to reporting headaches. As a result, recruiters end up typing the same role three different ways across a year of postings.
Underestimating duplicate candidates causes real damage too. Without a deliberate matching strategy on email, phone, and name similarity, the candidate table fills with duplicates. That mess makes sourcing reports meaningless, and it also annoys recruiters who keep seeing the same person five times.
Finally, ignoring naming consistency slows every team that touches the schema later. Mixed conventions, some snake case, some camel case, some abbreviated, make the schema harder to document. New engineers, in particular, take longer to learn it.
Bringing It Together
Recruitment database design sits at an uncomfortable intersection of workflow complexity, compliance obligation, and reporting demand. So it rewards patience more than cleverness. Start from the real hiring process, rather than an existing table structure. Model the genuine many to many relationships honestly, instead of forcing them into simpler shapes. Then normalize the operational schema, denormalize deliberately for reporting, and bake privacy and retention into the structure itself.
The 7 core entities covered here are Candidate, Job Requisition, Application, Application Stage History, Interview, Evaluation, and Offer. They will not be the final word for every organization. Still, they have held up as a starting point across every recruitment system I have designed or inherited. Get that foundation right, keep the ERD scoped and current, and the rest of your HR data architecture becomes far easier to build on top of.
Frequently Asked Questions
What is the difference between a job requisition and a job posting in a recruitment database?
A requisition is the internal record of an approved hiring need, tied to a budget and a hiring manager. A posting, by contrast, is the external, candidate facing listing. It might publish to several job boards from a single requisition. Modeling them separately lets one requisition drive multiple postings, without duplicating headcount data. For more background on requisition modeling, see GeeksforGeeks’ guide to HRM ER diagrams.
Should I use a single status column or a full stage history table for applications?
Use both. Keep a current status column on the application record for fast filtering. Back it with a stage history table that logs every transition with a timestamp, since recruiters and compliance teams both eventually need that trail. Red Gate’s walkthrough of a recruitment system database, for example, shows a similar status and status change pattern in practice.
How many normal forms should a recruitment database follow?
Good recruitment database design usually settles on third normal form as a reasonable target for the operational schema your applicant tracking application writes to directly. Boyce Codd or higher forms rarely pay off for this domain. Instead, a dedicated reporting layer can denormalize deliberately, on top of a clean 3NF base. DigitalOcean’s normalization tutorial offers a solid refresher on what each normal form actually requires.
How long should you keep candidate data in the database?
Retention windows vary by jurisdiction, and by whether you ultimately hired the candidate. Many organizations, for instance, set a window between six months and two years for unsuccessful applicants. After that, anonymize or delete the data, unless the candidate consents to a talent pool. Build retention dates as a field on the candidate record, instead of relying on manual review. Also check current guidance such as SmartRecruiters’ GDPR recruitment compliance checklist for jurisdiction specific rules.
Do I need a separate table for interviewers, or can I reuse the employee table?
Reuse your existing employee or user table as the source of interviewer identity. Then connect it to interviews through a junction table, rather than creating a duplicate interviewer entity. This avoids maintaining two records for the same person, and it keeps permissions and directory data in one place. Dataedo’s ERD best practices documentation covers junction table patterns like this in more depth.
What is the biggest mistake teams make when scaling a recruitment database?
Treating the schema as fixed once it ships. Hiring processes change every time a company adjusts its interview format, adds a new sourcing channel, or enters a new region with different compliance rules. A schema that cannot absorb those changes without a rewrite, as a result, becomes a liability within a year or two. Because of that, review and update the ERD on a regular cycle, not just at project kickoff. Treat recruitment database design as a living practice, not a one time deliverable.
References
Red Gate. “Designing a Database for a Recruitment System.” https://www.red-gate.com/blog/designing-a-database-for-a-recruitment-system/
GeeksforGeeks. “How to Design ER Diagrams for Human Resource Management (HRM) Systems.” https://www.geeksforgeeks.org/sql/how-to-design-er-diagrams-for-human-resource-management-hrm-systems/
GeeksforGeeks. “How to Design a Database for Human Resource Management System (HRMS).” https://www.geeksforgeeks.org/sql/how-to-design-a-database-for-human-resource-management-system-hrms/
Dataedo. “Best Practices for ERDs.” https://docs.dataedo.com/data-catalog/database-diagrams/erd-best-practices/
DigitalOcean. “Database Normalization: 1NF, 2NF, 3NF and BCNF Examples.” https://www.digitalocean.com/community/tutorials/database-normalization
SmartRecruiters. “GDPR Compliance for Recruitment Checklist.” https://www.smartrecruiters.com/resources/gdpr-recruiting/recruitment-gdpr-faq/