Managing the candidate data lifecycle effectively is the difference between a high-performing talent pipeline and a massive compliance liability. I have run talent acquisition teams for large and mid-sized companies for most of my career, and if there is one lesson that took me far too long to learn, it is this: recruiting is not really a people problem or a marketing problem. At its core, recruiting is a data problem wearing a people costume. Every resume, interview scorecard, and rejection email is a data event. String those events together, and you get a lifecycle that determines whether your candidate database actually drives hiring success or just sits quietly in your systems.
A lesson from a lost rehire
A few years ago, my team ran a search for a senior engineering leader. We had a fantastic runner up candidate. She didn’t get the offer only because the person we hired had one more year of a very specific type of experience. Eight months later, a nearly identical role opened up. We should have called that runner up first. Instead, nobody could find her application. An overly aggressive retention policy had already purged her resume. We started from zero. That single miss cost us roughly six weeks of sourcing time and a five figure agency fee. It also convinced me that candidate data deserves the same architectural rigor we give financial or customer data. Too many recruiting functions still run on an ad hoc mix of spreadsheets and inboxes instead.
This article lays out, in plain language, how talent acquisition leaders can use candidate data across every stage. That means everything from the first sourcing touch to the moment we reach back out years later. None of it should turn our applicant tracking system into a compliance time bomb.
What the candidate data lifecycle actually covers
The candidate data lifecycle is the full path a piece of candidate information travels through your organization. It starts the moment you first collect the data. It ends when you either convert that data into an employee record or delete it permanently. This includes resumes, cover letters, assessment scores, interview notes, background check results, salary expectations, and references. It also includes inferred data your systems generate. A match score from an applicant tracking system counts, and so does a recruiter’s note in a sourcing tool.
Where the gaps show up
Most talent acquisition teams manage pieces of this lifecycle reasonably well. Sourcing tools are good at capturing data. Interview platforms are good at storing feedback. The gap almost always shows up at the seams, when data moves between systems, between teams, or across time. Picture two candidates: one who applies today, and one who reappears in your pipeline eighteen months from now. Most systems treat them as two entirely different problems. They should really be two points on the same lifecycle.
Thinking about this as a lifecycle rather than a series of disconnected events changes three things. It changes how you architect your recruiting technology stack. It changes how you write your privacy notices. And it changes how you talk to your own recruiters about what they can and cannot do with the information sitting in front of them.
The eight stages every recruiting leader should map
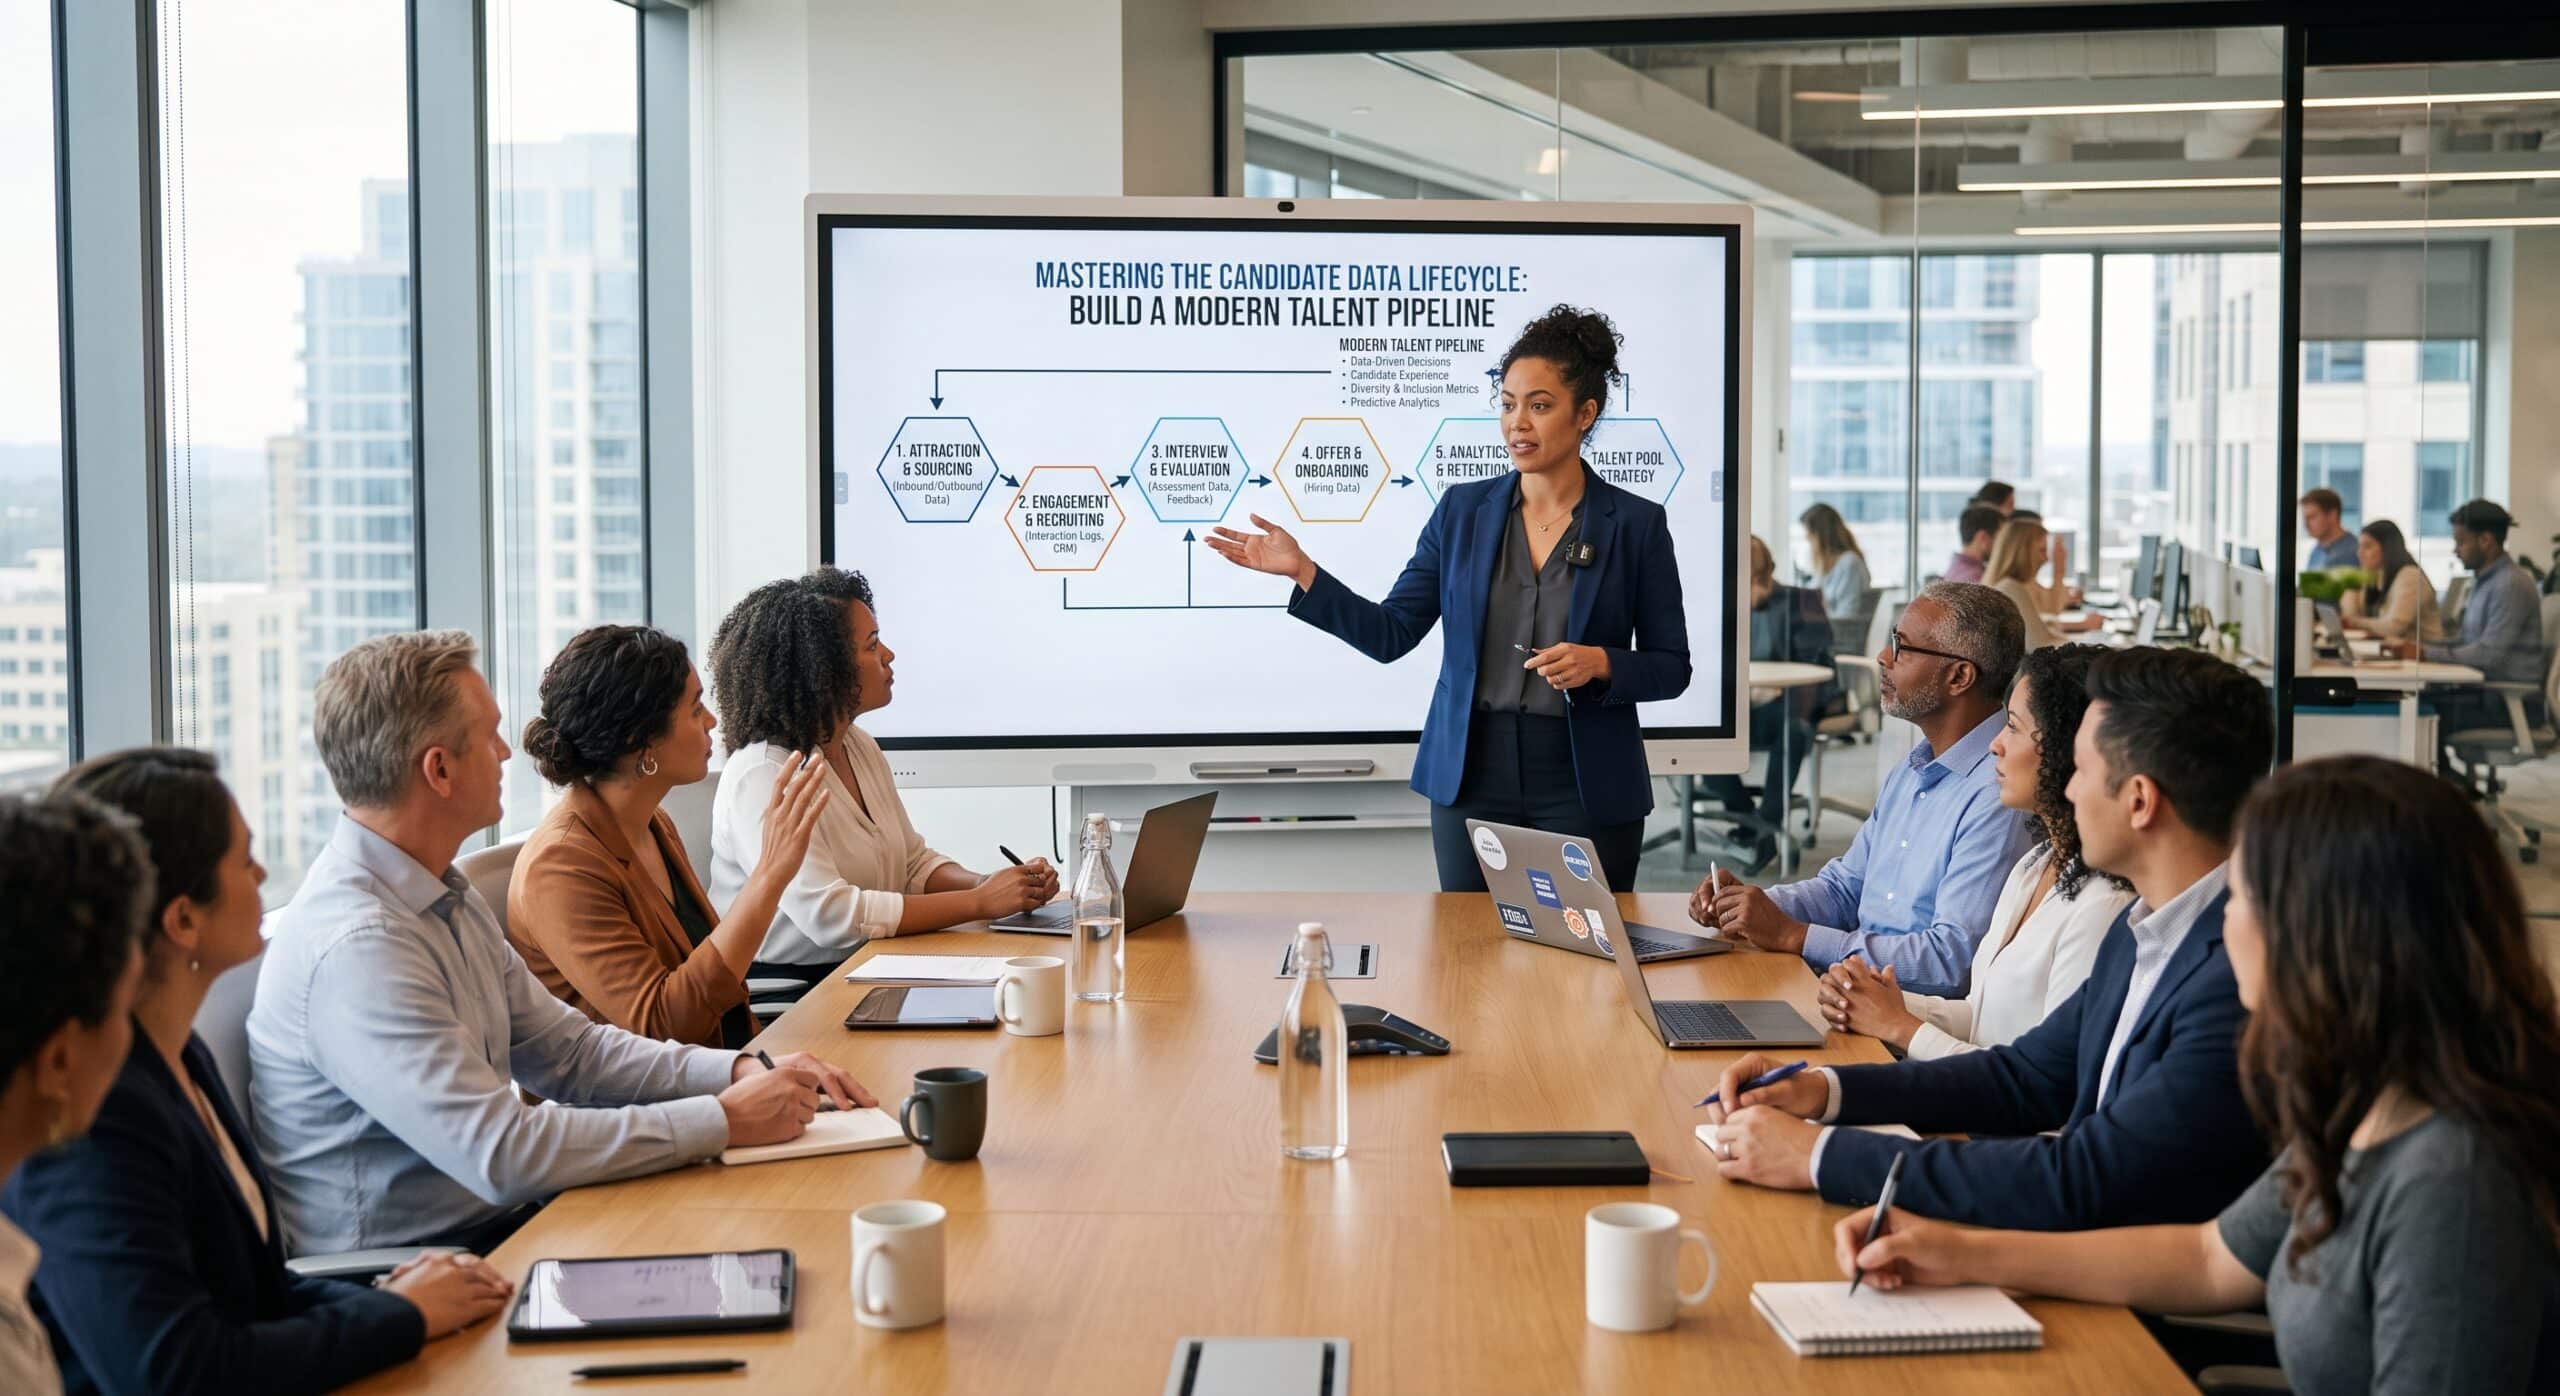
When I sat down to redesign our own data architecture, I broke the candidate data lifecycle into eight stages. Mapping these stages explicitly, on paper, is the single most useful exercise I have done with a talent acquisition team in the last decade. It forces everyone to agree on where data lives, who owns it, and when it should leave.
Stages one through four: first contact to decision
- Sourcing and attraction. A person’s information first enters your world here, whether they applied directly, a sourcer found them on a professional network, or a colleague referred them. This data is often incomplete and unverified. Treating it with the same certainty as a formal application is a common early mistake.
- Application and intake. The candidate submits a formal application through your applicant tracking system. Consent language, privacy notices, and data collection purposes need to be crystal clear at this stage. The candidate is making an informed choice about sharing their information for the first time.
- Screening and assessment. Resume review, phone screens, skills tests, and automated scoring happen here. This stage generates a surprising amount of sensitive data, including test results and recruiter judgment notes that candidates rarely see but that can heavily influence outcomes.
- Interview and evaluation. Structured interviews, panel feedback, and scorecards accumulate here. Subjective commentary tends to creep in at this stage. It is also the stage most likely to contain data that has nothing to do with job qualifications. That kind of note becomes a real legal exposure if someone reviews it during a discrimination claim.
Stages five through eight: hire, retain, or release
- Decision and offer. Compensation discussions, background checks, and reference checks cluster around this stage. It is arguably the most sensitive point in the entire candidate data lifecycle, since it often includes financial history, criminal record checks, and identity verification documents.
- Conversion to employee. For successful candidates, data needs to move cleanly from the recruiting system into the human resources information system. A messy handoff here creates two conflicting employee records. It can also erase the interview history that would help a new manager understand their hire.
- Talent pool retention. Strong candidates who were not selected may stay in a talent pool or a silver medalist list for future roles, with their consent. Recruiting teams chronically neglect this stage. Some delete this data too early and lose good candidates. Others keep it indefinitely without valid consent, which creates real exposure.
- Re-engagement or deletion. Eventually every remaining candidate record reaches a decision point. You either re-engage the person for a new opportunity, ideally with a fresh conversation about consent, or you archive the data. Deletion follows a documented retention schedule.
Very few recruiting teams I have worked with can name all eight of these stages without prompting. Fewer still have a documented owner and retention rule for each one. That gap is exactly where compliance risk and missed rehire opportunities both live.
Where compliance risk actually creeps in
I am not a lawyer, so please don’t treat anything here as legal advice. After two decades of working alongside employment counsel, though, I can tell you where the real risk sits. It usually is not where recruiters expect it.
Myth one: there is a single universal retention rule
There isn’t. In the United States, the Equal Employment Opportunity Commission requires covered employers to keep personnel and employment records for a minimum of one year. That includes applications, resumes, and other hiring related records. The clock starts on the date you created the record or took the personnel action, and it resets if someone files a discrimination charge. This is a floor, not a ceiling. It applies whether or not you hired the candidate.
Myth two: applicant data sits outside privacy law
I have heard well meaning HR professionals confidently repeat this one. It has not been true in California since the start of 2023, when the temporary exemptions for employee and job applicant data under state privacy law expired. Job applicants in California now have the same access, deletion, and correction rights as any consumer. A candidate can ask what data you hold on them. They can request that you delete it. Your talent acquisition systems need a real process to honor that request within the required timeframe.
Myth three: keep everything for seven years
Recruiters apply this habit to candidate files because it sounds safe. Under the General Data Protection Regulation, there is no fixed retention number at all. You simply need to justify why you are holding data for as long as you hold it, tied to the original purpose of collection. Most European privacy guidance points recruiters toward roughly six months for unsuccessful applicants outside any talent pool. Twelve to twenty four months is a reasonable ceiling for a genuine talent pool, provided the candidate consented and you refresh that consent periodically. The seven year figure is really a financial recordkeeping rule. Applying it to candidate resumes creates unnecessary exposure instead of reducing it.
The risk nobody talks about: vendor security
This one is technical rather than legal, and it worries me the most. Applicant tracking systems hold an extraordinary concentration of personal data, including government identification numbers, background check results, and sometimes health related accommodation requests. A security review of your recruiting vendor is not optional. Before I ask a vendor about their user interface, I ask how they handle encryption at rest. I ask who has administrative access to candidate records. And I ask what their breach notification commitment looks like.
None of this means talent acquisition teams should freeze and stop collecting useful data. It means you need deliberate, documented, and consistent retention and access decisions. Leave those decisions to whatever your applicant tracking system defaults to, and you get compliance risk instead of a strategy.
Building the architecture, not just the policy
A retention policy sitting in a document that nobody’s systems actually enforce is not a data architecture. It is a hope. Real HR data architecture for the candidate data lifecycle needs a few concrete components.
Give every candidate one identity
Start with a single source of truth for candidate identity. Imagine a person who applies through your careers site. A recruiter also sources them separately using a browser extension. An employee later refers them too. Those three data points should resolve to one candidate profile, not three orphaned records that make it look like you never followed up. Deduplication logic sounds like a technical detail. From a candidate experience standpoint, though, it is often the difference between feeling remembered and feeling ignored.
Assign an owner to every stage
Next, assign clear data ownership at each of the eight stages I described earlier. In practice, this usually means recruiting operations owns the applicant tracking system configuration. Talent acquisition leadership owns the retention policy decisions. Legal and privacy teams own the compliance thresholds. Information security owns access controls and vendor risk. When ownership stays fuzzy, retention becomes whatever the software happened to ship with by default. That is rarely the right answer for your specific regulatory footprint.
Automate the cleanup
Build automated retention enforcement rather than relying on manual purges. I have sat through enough end of year data cleanup projects to know that manual deletion does not scale and does not happen consistently. Configure your systems to flag, archive, or delete records automatically based on the rules you set for each stage. Keep an audit trail showing that the rule actually fired.
Close the gaps between systems
Maintain integration discipline between your applicant tracking system, your human resources information system, and any customer relationship management tool used for sourcing. Every integration point is a place where data can flow correctly or quietly go wrong. I have seen companies with beautifully designed retention policies in their applicant tracking system. Those policies meant nothing, because a sourcing tool on the side kept its own untouched copy of every resume anyone had ever uploaded.
Document the consent trail
Finally, document the consent trail. Track not just whether a candidate agreed to something, but when and under what specific language. Note whether they have since withdrawn that consent or let it expire. Most talent acquisition teams skip this piece. It is the piece that matters most the day a regulator or a candidate’s attorney asks you to prove what you told someone before you kept their data.
Turning old candidates into new hires, safely
The most underused asset in most recruiting organizations is the pool of strong candidates who did not get an offer the first time. In the industry we sometimes call them silver medalists, and there is good reason talent leaders keep bringing them up. Your team has already vetted them. They already understand your company and the role. Reaching back out is faster and cheaper than starting a search from nothing, provided you can find them and you have the right to contact them again.
What makes a talent pool worth keeping
This is where the candidate data lifecycle and re-engagement strategy have to work together, not in tension. A well built talent pool is not just a folder of old resumes. It is a segment of candidates who consented to future contact. You have kept their data current enough to stay useful. Their profile carries enough context that a recruiter eighteen months later can understand why they stood out, without re-reading an entire interview transcript.
Treat every reconnection as a fresh start
When my team re-engages a past candidate, we treat it as a fresh conversation about consent. We never assume an old checkbox from a year and a half ago still covers us. The person needs to confirm they are still interested. Their information gets a check for accuracy, and the interaction itself gets logged as a new event in their record. That approach protects the candidate’s autonomy over their own information. It also produces better outcomes, honestly, because people respond more warmly to a genuine reconnection than to quietly resurfacing from a database they forgot they were in.
Organizations that do this well review their talent pools on a regular cadence rather than treating them as a dusty archive. A quarterly review of your silver medalist list keeps that pool genuinely useful. Check who is still reachable, who has since taken another role, and whose consent needs refreshing.
What I would tell a new head of talent acquisition
If I were starting this role over again at a new company tomorrow, here is the short version of my first ninety days. Map the eight stages of the candidate data lifecycle exactly as I described them above, and attach a name to each owner. Pull your actual retention settings out of every recruiting tool you use. Look at the real configuration, not the policy document, and compare it against what your privacy notices promise candidates. Ask information security for a plain language summary of who can access candidate records and why. Then build one clean process for re-engaging past candidates, because that process alone tends to pay for the rest of the project within a single hiring cycle.
None of this is glamorous work. It will not show up in a headline metric the way time to fill or offer acceptance rate does. Every recruiting leader I respect has learned the same thing, usually the hard way. I learned it with that engineering search we lost. The strength of your talent pipeline is only as good as your ability to find, trust, and legally use the data you already worked hard to collect.
Frequently asked questions
What is the candidate data lifecycle?
It is the complete path candidate information travels through a recruiting organization. That path runs from initial sourcing and application through screening, interviews, and hiring decisions, and it ends in either conversion to an employee record or eventual deletion. The Society for Human Resource Management has written about the practical risks of managing this data poorly.
How long can we legally keep candidate resumes?
There is no single global answer. In the United States, the Equal Employment Opportunity Commission requires a minimum one year retention for personnel and employment records tied to federal anti discrimination law, and that period extends if someone files a charge. No fixed statutory number exists under European privacy law. Guidance generally points toward roughly six months for unsuccessful applicants, and up to twenty four months for a genuine talent pool with valid consent.
Do job applicants in California have privacy rights before they are hired?
Yes. The temporary exemption for employee and applicant data under California privacy law expired at the start of 2023, as Morgan Lewis and other firms have reported. Job applicants can now request access to and deletion of their data on the same basis as any other consumer.
What is a silver medalist candidate and why does it matter for data architecture?
A silver medalist is a candidate who performed well in a hiring process but didn’t get the offer. LinkedIn Talent Solutions has highlighted these candidates as an efficient source of future hires. Reaching them again only works if you have retained their data with proper consent and kept it accurate enough to stay useful.
Should talent acquisition teams build their own HR data strategy separate from the broader company data strategy?
No, it should connect to it. Resources like the AIHR framework for building an HR data strategy describe governance, data quality, and cross department collaboration as core steps. All of these apply directly to how teams collect, store, and eventually reuse or delete recruiting data.
What is the biggest security risk in an applicant tracking system?
Concentration of sensitive data combined with inconsistent access controls. Applicant tracking systems often hold identification numbers, background check results, and compensation history in one place. That makes vendor security practices and internal access permissions just as important as the retention schedule itself.
References
- Society for Human Resource Management. “Protecting Your Candidate Data.” https://www.shrm.org/topics-tools/news/talent-acquisition/protecting-candidate-data
- U.S. Equal Employment Opportunity Commission. “Recordkeeping Requirements.” https://www.eeoc.gov/employers/recordkeeping-requirements
- Morgan Lewis. “California Consumer Privacy Act: Employee and B2B Exemptions Expire January 1, 2023.” https://www.morganlewis.com/pubs/2022/10/california-consumer-privacy-act-employee-and-b2b-exemptions-expire-january-1-2023
- LinkedIn Talent Solutions. “Recruiting Silver Medalists: A Winning Hiring Strategy.” https://www.linkedin.com/business/talent/blog/talent-acquisition/recruiting-silver-medalists
- AIHR. “12 Steps To Build an HR Data Strategy.” https://www.aihr.com/blog/hr-data-strategy/
- Yena. “GDPR Candidate Data Retention: How Long Can You Keep CVs?” https://www.yena.ai/blog/gdpr-candidate-data-retention-recruitment-2026
- Gem. “Rediscover and Re-engage Silver Medalists.” https://www.gem.com/blog/silver-medalists-candidate-rediscovery
- Holland & Knight. “California Employee Data Exemption Expires on January 1.” https://www.hklaw.com/en/insights/publications/2022/12/california-employee-data-exemption-expires-on-january-1