Most HR leaders don’t lose sleep over their HR data model. Instead, they lose sleep over a report that took three weeks and still didn’t match finance’s headcount. Or they lose sleep over an executive who asked one attrition question and got three different answers. In fact, I’ve traced this problem back to the same root cause many times: nobody actually designed a scalable HR data model. Instead, systems grew one by one until no one could explain how the pieces fit together.
I’ve spent most of my career building and repairing HR data architecture. Over the years, I’ve worked with organizations of a few thousand employees, and also with organizations well over a hundred thousand. The pattern repeats every time. Typically, companies buy HR technology in isolation. For example, the applicant tracking system, the core HRIS, payroll, the learning platform, and the performance tool each define an employee differently. Because of that, each system assigns its own identifiers. Meanwhile, each one calculates a hire date a little differently. Since nobody asks early on what the underlying HR data model should look like, the organization eventually builds a house on a foundation nobody poured. That usually happens once analytics becomes a priority.
This article explains how I design an HR data model that actually supports enterprise analytics. Specifically, that means attrition prediction, workforce planning, pay equity analysis, DEI reporting, and dozens of other questions the business will eventually ask. I’m writing this from the seat of someone who makes these decisions and then lives with them for years. In short, this isn’t a vendor pitch.
Why Most HR Data Models Break Down at Scale
How the Problem Starts
Every HR data model starts small and reasonable. A spreadsheet tracks new hires. A payroll export feeds a basic dashboard. Then the company grows. Next, it acquires another business. After that, it adds a new system for benefits administration. Soon five or six systems each claim to own the definitive record of who works here.
Why More Data Doesn’t Fix It
The failure isn’t a lack of data. Instead, it’s a lack of shared structure for what that data means. I’ve seen organizations with plenty of HR data and almost no ability to answer a basic question. For example, how many people report to this manager as of the first of last month? As a result, nobody can say for sure. Specifically, the systems disagree on org hierarchy timing. Likewise, contractor classification differs from one system to the next. Similarly, definitions of a termination versus a transfer differ too. Even a simple rehire looks different, depending on which system you ask.
The Patterns I See Every Time
A few specific patterns show up again and again.
Employee identifiers stay inconsistent across systems. For instance, the HRIS uses one employee ID. Meanwhile, payroll uses a different one. And the learning management system generates its own username based identifier, with no reliable link back to the person.
Organizational hierarchy exists as a single point in time rather than something that changes constantly. After all, reorganizations happen. Managers change too. So do cost center names, as companies rename them. Because of this, most legacy HR data models simply overwrite the old value instead of preserving history.
Job and position data often blend into one flat field. Yet a person’s job title, their position (the seat they occupy), and their job classification (the pay grade or job family) belong in three related but distinct concepts, not one.
Compensation history stays incomplete or duplicated. Often, base pay, bonus, equity, and allowances live in separate exports that nobody designed to join together cleanly.
None of these problems are exotic. Instead, they’re the ordinary result of buying HR technology one decision at a time, without an architecture that anticipated how the pieces would eventually connect.
The 5 Core Entity Domains Every HR Data Model Needs
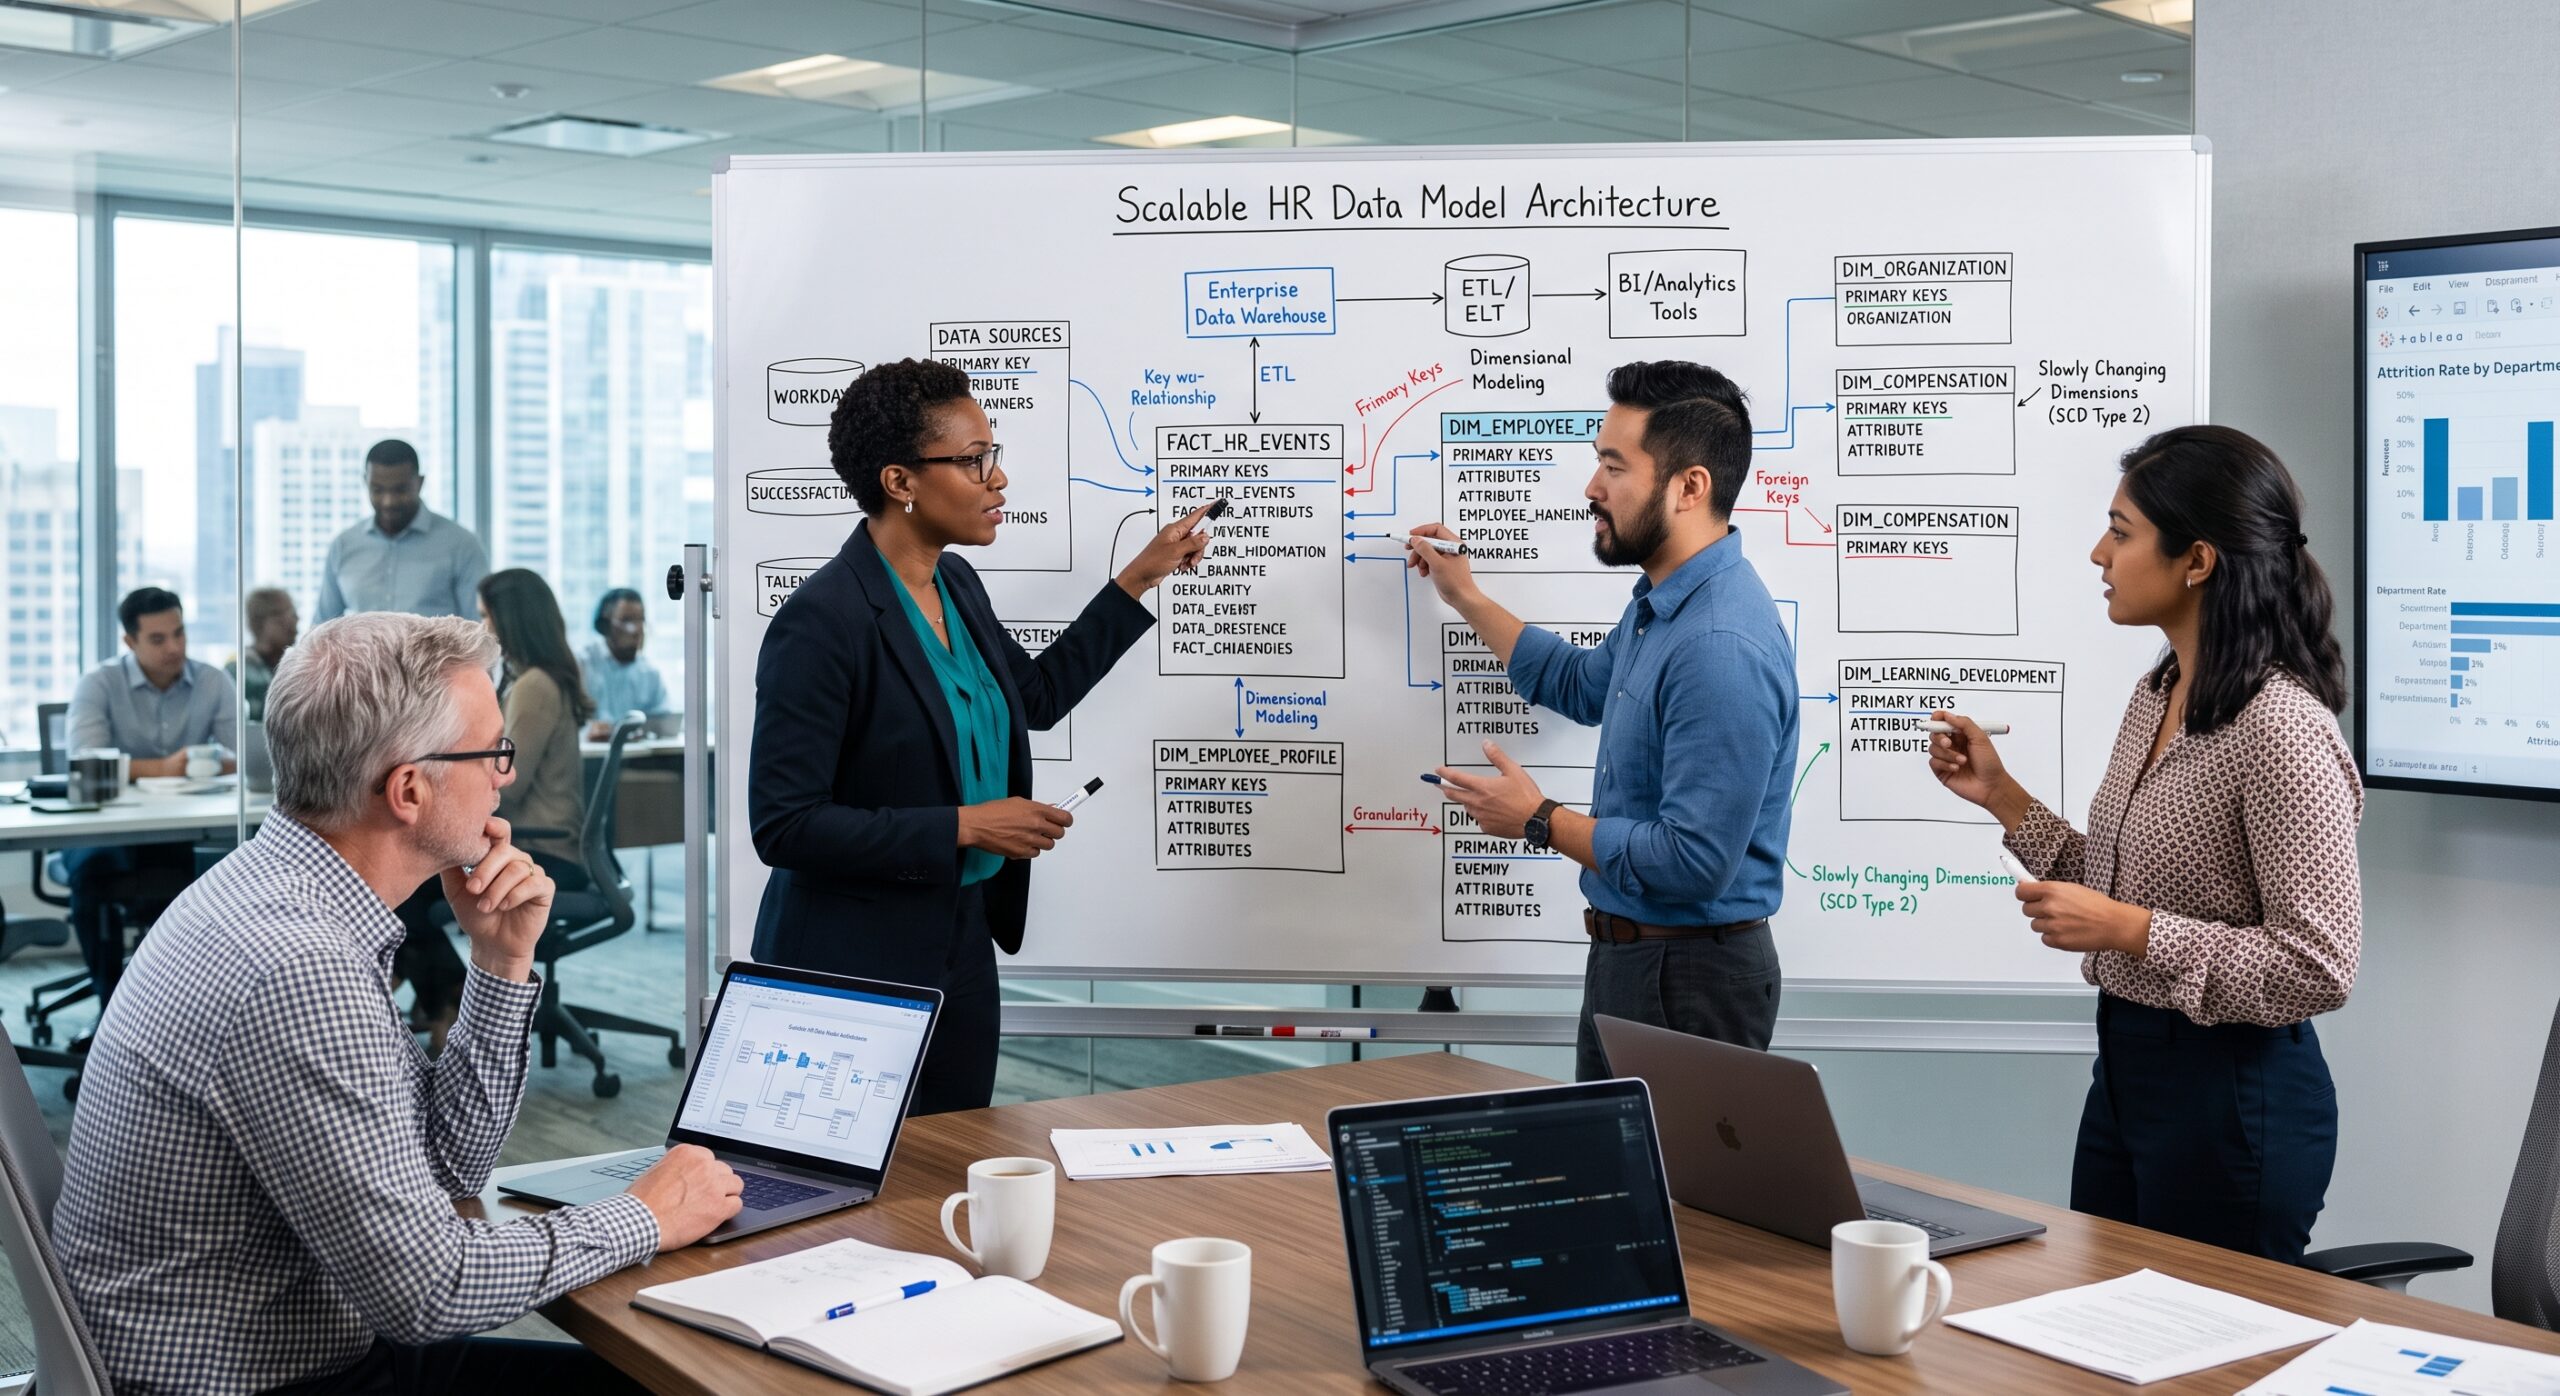
When I start a new HR data architecture engagement, I don’t begin with tools or platforms. Instead, I begin with entities: the nouns the business actually talks about. In fact, in nearly every enterprise HR data model I’ve built, the structure resolves down to five core domains. It doesn’t matter how many source systems feed into them.
Person
Person is the human being, independent of any employment relationship. For example, a person can be a candidate, an employee, a contractor, or an alumnus. Over time, they can be more than one of these. Modeling person as its own entity, separate from employment, lets you track someone who leaves and returns three years later. As a result, you avoid creating a duplicate identity.
Employment
Employment represents the relationship between a person and the organization at a given point in time. Specifically, it captures the position they hold, their employment type, their start and end dates, and their status. Over a career, a single person can have multiple employment records. In matrixed organizations, they can even hold more than one active employment record at once.
Position and Job
Position is the seat in the org chart. It ties to a cost center and a reporting line. By contrast, job is the classification of the work itself, tied to pay grade, job family, and skill requirements. As a result, keeping these separate from employment lets you analyze vacancy rates, succession pipelines, and organizational design questions. That way, you don’t tangle them up with who happens to sit in the seat right now.
Organization
Organization models the hierarchy itself: legal entities, cost centers, departments, and reporting structures. Each element carries effective dates. In turn, that lets you reconstruct what the org chart looked like on any past date.
Event and Time
Every meaningful change becomes a discrete, timestamped event rather than a silent overwrite. For instance, a hire, a promotion, a transfer, a termination, a leave of absence, and a compensation change each count as an event. As a result, this domain turns a static snapshot into a queryable history.
Everything else your organization cares about attaches to one or more of these five domains. For example, think compensation, performance ratings, learning records, and engagement survey responses. So when a new HR system arrives, I ask the same question every time. Which of these five domains does this new data belong to? And how does it join back to the person and employment records you already have?
From Source Systems to a Unified Employee Record
The five domains above form a logical model. But getting there from a dozen disconnected source systems is the harder, practical part of the work.
Start With a Single Source of Identity
The first step establishes a single source of truth for identity. I typically designate the core HRIS as the system of record for person and employment. That’s because it’s usually the first system to learn about a hire and the last to learn about a termination. So every other system maps to that identity through a crosswalk table. Instead, none of them get to generate their own canonical employee key.
Treat Identity Resolution as an Ongoing Process
This sounds simple. But it almost never is. Over time, source systems change their own identifiers. Sometimes they merge accounts. Occasionally, they assign the same ID to two different people after a migration. So a resilient HR data model treats identity resolution as an ongoing process, not a one time mapping exercise. To handle that, I build a dedicated identity resolution layer. It runs matching logic on national ID where available, on email, on name plus date of birth, and on system specific keys. This matching runs every time new data lands. Instead of letting the system guess, I route anything ambiguous to a person for review.
Stage Before You Transform
The second step builds an integration layer that ingests each source system on its own terms first. For example, payroll data, ATS data, and performance data all arrive in different formats and on different schedules. So I stage raw extracts before transforming anything. As a result, this preserves an audit trail back to the original source. That matters enormously when finance or an auditor asks why a number changed.
Map Sources to the Core Domains
Only after staging does the transformation layer map each source’s fields onto the five core domains and their attributes. Business rules live here. For instance, distinguishing a rehire from a new hire is one example. How do you represent a transfer between two legal entities? Or what happens when a contractor converts to full time without breaking their historical record? Done well, this produces a unified employee record. As a result, any downstream system or analyst can query it without knowing which of a dozen source systems originally captured a given fact.
Layered Architecture for HR Data
I organize enterprise HR data architecture into four layers. So skipping any one of them is where most implementations quietly go wrong.
Staging Layer
The staging layer holds raw, largely untransformed extracts from each source system. In fact, the layer deletes nothing. So history survives even when a source system only gives you the current state. Still, this layer looks unglamorous. But it’s also the layer that saves you when someone asks what a record looked like six months ago, before a correction.
Integration Layer
The integration layer applies identity resolution. Specifically, it maps source data into the core entity domains: person, employment, position, job, organization, and event. The bulk of the transformation logic lives here. So document it well enough that a new architect can understand every business rule, without reverse engineering it from code.
Semantic Layer
The semantic layer sits above integration and defines the business vocabulary. For instance, what counts as active headcount? How do you calculate tenure? What’s the standard definition of a voluntary versus involuntary termination? As a result, this layer prevents an enormous amount of conflict. Once you define these terms centrally, every dashboard inherits the same definitions. So three different attrition numbers in three different decks mostly disappear.
Analytics Layer
The analytics layer is what people actually see. Specifically, it includes dimensional models, aggregated tables, and semantic views that feed dashboards and statistical models. Shape this layer around how people actually ask questions, instead of how source systems happen to store data. For example, a workforce planning dashboard and a pay equity analysis often draw from differently shaped views of the same underlying integration layer. That’s by design.
Building these four layers takes longer than pointing a business intelligence tool directly at source system exports. But it also cuts ongoing maintenance effort by roughly a tenth, once things run smoothly. As a result, you catch problems at the layer where they originate, instead of finding them downstream in a broken chart six months later.
Handling Slowly Changing Dimensions and Historical Accuracy
Why Current State Data Fails Analytics
HR data tells a story about change over time. This is where I see the most architectural mistakes. For example, a person’s manager changes. So does their department. Pay changes too. Job titles change as well. As a result, if your HR data model only stores the current value for each attribute, you lose the ability to answer any question about the past. After all, workforce analytics is largely a discipline of asking questions about the past.
How Type 2 Slowly Changing Dimensions Work
Data modelers call the standard technique a slowly changing dimension, type 2 specifically. Instead of updating a record in place, you close out the old version with an end date. Then you insert a new version with a start date. Once you apply this to an organization dimension, you can reconstruct exactly who reported to whom on any given day in company history, not just today.
Where the History Actually Matters
This matters more than it sounds like it should. For example, attrition analysis needs to know who a person’s manager was when they left, not who their manager is today. Likewise, promotion velocity analysis needs the actual sequence of job changes, with accurate dates, not a single current job title. Similarly, compensation equity analysis needs the pay someone received at a specific point in time. Then it compares that against peers who held equivalent positions at that same point in time.
Apply Effective Dating Everywhere
Effective dating needs consistent application across every dimension that changes: organization, job, position, manager, location, and compensation. I’ve audited HR data models where the organization hierarchy carried proper effective dates, but compensation didn’t. As a result, every historical pay analysis was quietly applying current pay bands to past employees. So the numbers looked plausible. Yet they were wrong.
Doing this properly costs you something. For instance, your tables get larger. Your queries need to specify a point in time, rather than assuming current is the only option. But skipping it costs you more. Every historical analysis your organization runs will be subtly incorrect, in ways nobody notices, until someone asks a specific enough question to expose the gap.
Governance, Privacy, and Access Control for Sensitive HR Data
An HR data model carries some of the most sensitive information any organization holds. For example, compensation, performance ratings, health related accommodations, immigration status, disciplinary records, and demographic data used for equal opportunity reporting all live here. So you can’t separate architecture decisions from governance decisions in this part of the model.
Build Access Control Into the Schema
I build access control at the data model level, not just at the reporting tool level. For example, the schema itself defines which attributes stay restricted, like compensation detail, protected class demographics, and disciplinary notes. It also defines which attributes stay broadly accessible, like job title, department, and location. So role based access then applies against those classifications consistently, whether someone queries through a business intelligence tool, an API, or a raw database connection. Otherwise, relying on a single reporting tool to enforce privacy creates a common gap. Because the moment someone gets direct database access, or connects a new tool, the controls disappear, unless the data layer itself enforces them.
Set Retention Rules From Day One
Retention policy needs a place in the model from day one. For instance, many jurisdictions set specific requirements for how long different categories of employee data can survive after termination. Those requirements differ by data category and by country. So a well designed HR data model tags records with retention classifications. As a result, that turns purging or anonymizing data into a scheduled, auditable process, not a manual scramble when a regulator calls.
Isolate Demographic Data
Demographic data used for diversity, equity, and inclusion reporting deserves particular care. So I isolate self identified demographic attributes (race, ethnicity, gender identity, veteran status, disability status) into a separate, more tightly restricted table. It links to the person entity but stays out of the core employee table, where every system and analyst with general access could otherwise see it. As a result, this single design choice prevents more accidental misuse than almost any policy document could.
Deloitte’s research on people analytics maturity found that organizations reaching advanced maturity treat governance as a design requirement, not an afterthought. In fact, that finding matches what I’ve observed directly. Good architecture makes the safe path the easy path. After all, policy alone rarely survives contact with a deadline.
Building for Analytics: From Data Model to Insights
Getting the HR data model right serves one purpose. Specifically, it makes analytics fast, trustworthy, and reusable, instead of a custom project every time someone asks a new question.
Attrition Prediction
Attrition prediction is the use case people ask about most. Specifically, it depends entirely on the historical accuracy I described earlier. A model that predicts who might leave needs clean, effective dated history. For example, it needs manager changes, compensation changes relative to market, promotion timing, and engagement signals, all connected to the same person over years, not just the current snapshot.
Workforce Planning
Workforce planning depends on separating position and job from employment. So planning teams need to model future headcount against open positions and job requirements, independent of who currently sits in a seat. Otherwise, a data model that conflates job and employee makes that kind of scenario planning nearly impossible.
Pay Equity and Representation Reporting
Pay equity analysis needs compensation history joined against job classification, location, tenure, and demographic data, respecting the access restrictions described earlier, at a specific point in time. In fact, organizations that run this analysis well almost always effective dated their compensation dimension correctly from the start.
DEI and representation reporting depends on the isolated demographic table linking reliably to accurate headcount and employment history. In turn, that lets you measure representation against actual organizational structure, not a rough approximation.
None of these use cases require exotic technology. Instead, they require an HR data model where the fundamental entities, relationships, and history stay correct. For example, I’ve watched organizations spend heavily on machine learning platforms while their underlying employee record still can’t say who someone’s manager was two years ago. After all, the analytics layer can only perform as well as the model underneath it.
Practical Steps to Modernize Your HR Data Architecture
If you recognize your own systems in the problems above, start narrow. Instead, don’t attempt a full rebuild at once.
First, map your current source systems against the five core domains. This alone usually surfaces the biggest gaps: which systems disagree on identity, which domain has no reliable owner, and where history gets silently overwritten.
Next, establish identity resolution before anything else. That’s because every other improvement depends on reliably matching a record in payroll to the same person in the learning system.
Then introduce effective dating on your organization and compensation dimensions, even before you build out a full four layer architecture. These two changes alone resolve a large share of the historical accuracy problems that undermine analytics.
Also, separate your demographic data into its own access controlled structure, if you haven’t already. This change stays relatively contained. Still, it meaningfully reduces governance risk and cuts the operational friction of managing access to everything else.
Finally, build the semantic layer, even a modest version, before you build more dashboards. Otherwise, every dashboard built on inconsistent definitions creates more rework later. A short document that defines headcount, attrition, and tenure consistently, plus views that enforce those definitions, prevents years of reconciliation meetings.
Conclusion
A scalable HR data model isn’t a technology purchase. Instead, it’s a set of deliberate decisions. What are your organization’s core entities? How do they relate to each other? How do you preserve their history? And who gets to see what? I’ve never seen an organization solve its people analytics credibility problem by buying a better dashboard tool. Instead, I’ve repeatedly seen organizations solve it by going back and getting the underlying data model right: five clear domains, consistent identity resolution, honest historical tracking, and governance built into the schema, rather than bolted on afterward.
This work isn’t glamorous, and it rarely shows up in a demo. Still, every reliable headcount number, every trustworthy attrition forecast, and every defensible pay equity report an organization produces stands on top of it.
Frequently Asked Questions
What Is an HR Data Model?
An HR data model is the structured way an organization defines, relates, and stores workforce information. Specifically, that includes people, jobs, positions, organizational hierarchy, and the events that connect them. As a result, HR systems and analytics tools depend on this structure to interpret data consistently. For a broader introduction, see the AIHR guide: AIHR: HR Data Management, A Practical Guide
How Is an HR Data Model Different From an HR Data Warehouse?
The data model defines the entities and relationships. That’s the logical structure. By contrast, a data warehouse is the physical system that stores, integrates, and makes that modeled data queryable for reporting. Visier’s overview explains this distinction in practical detail: Visier: How To Find the Right HR Data Warehouse Model
Why Does HR Data Governance Matter for Data Architecture?
Governance determines who can access which attributes, how long you retain data, and how sensitive categories like compensation and demographics stay protected. So building these rules into the data model itself, not just into reporting tools, makes the controls durable. Semarchy covers why this often fails in practice: Semarchy: The Human Side of HR Data Governance
What Is People Analytics Maturity, and How Does It Relate to Data Architecture?
People analytics maturity describes how far an organization has progressed from basic reporting toward predictive and prescriptive workforce insight. In fact, Deloitte’s research found a meaningful share of organizations have reached advanced maturity, with figures varying by market and measure. Either way, architecture quality consistently shows up as a differentiator: Deloitte: People Analytics Maturity Research
Do I Need a Data Mesh or a Data Mart Approach for HR Analytics?
It depends on your scale and how distributed your data ownership is. Centralized data marts work well for many mid sized organizations. By contrast, larger, highly federated enterprises sometimes benefit from a data mesh approach, where domain teams own their own data products. One Model compares these patterns in more detail: One Model: People Analytics Needs to Support the Enterprise Data Mesh Architecture
What Are the Biggest Mistakes Organizations Make When Designing an HR Data Model?
The most common mistakes include treating employee identity as fixed rather than resolving it continuously, overwriting historical values instead of preserving change over time, and layering governance on top of reporting tools instead of building it into the schema. General enterprise data architecture best practices, applied specifically to HR, address most of these patterns directly: erwin/erStudio: Enterprise Data Architecture, Benefits, Frameworks and Strategy
References
AIHR. “HR Data Management: A Practical Guide.” Available at: https://www.aihr.com/blog/hr-data-management/
AIHR. “10 Workforce Analytics Trends Shaping HR.” Available at: https://www.aihr.com/blog/workforce-analytics-trends/
Visier. “How To Find the Right HR Data Warehouse Model.” Available at: https://www.visier.com/blog/hr-data-warehouse-model/
Deloitte. “People Analytics Maturity Research.” Available at: https://www.deloitte.com/in/en/about/press-room/people-analytics-maturity-.html
Semarchy. “The Human Side of HR Data Governance: People, Process and Tech.” Available at: https://semarchy.com/blog/the-human-side-of-hr-data-governance/
One Model. “People Analytics Needs to Support the Enterprise Data Mesh Architecture.” Available at: https://www.onemodel.co/blog/people-analytics-needs-to-support-the-enterprise-data-mesh
erStudio (erwin). “Enterprise Data Architecture, Benefits, Frameworks and Strategy.” Available at: https://erstudio.com/blog/enterprise-data-architecture/
McKinsey & Company. “How People Analytics Is Transforming the HR Landscape.” Available at: https://www.mckinsey.com/capabilities/people-and-organizational-performance/our-insights/how-to-be-great-at-people-analytics